What Is an LLM Wiki — and Should You Build One?
The Karpathy LLM wiki went viral for a reason. Here's what it actually is, who it's built for, and whether a solo operator needs one.
1. What an LLM Wiki Is — the Plain-Language Version
Hi, I'm Kostja. I'll be honest — when Karpathy's tweet started circulating in early April 2026, my first reaction was "wait, is this actually new?" I've been tinkering with personal knowledge setups for a while — Obsidian vaults, custom GPT instructions, note-dumping workflows — and I knew what RAG was. So the first time I skimmed the posts about his LLM wiki, I half-dismissed it. Then I actually read the gist. Okay. I get why it went viral.
Let me strip the jargon out, because the concept is genuinely simple once you see it. Most of us interact with AI and documents like this: you upload a PDF or paste some notes, you ask a question, the AI finds the relevant chunks and generates an answer. That's RAG — Retrieval-Augmented Generation. It works. But it has one critical flaw: every question starts from scratch. The AI isn't building up knowledge between queries; it's rediscovering things every single time.
An LLM wiki flips that. Instead of searching raw documents on the fly, you ask the LLM to pre-compile your sources into a structured wiki — a directory of linked markdown files. After that, when you ask a question, the AI isn't digging through raw PDFs; it's navigating a knowledge base that has already synthesized them. The framing that made the rounds at the time — with RAG you cook every time you're hungry, with a wiki you build a kitchen that keeps improving its recipes — gets the idea across well enough, even though it doesn't appear in the gist itself.
How It Works: Raw Sources, Compiled Wiki, Schema Layer
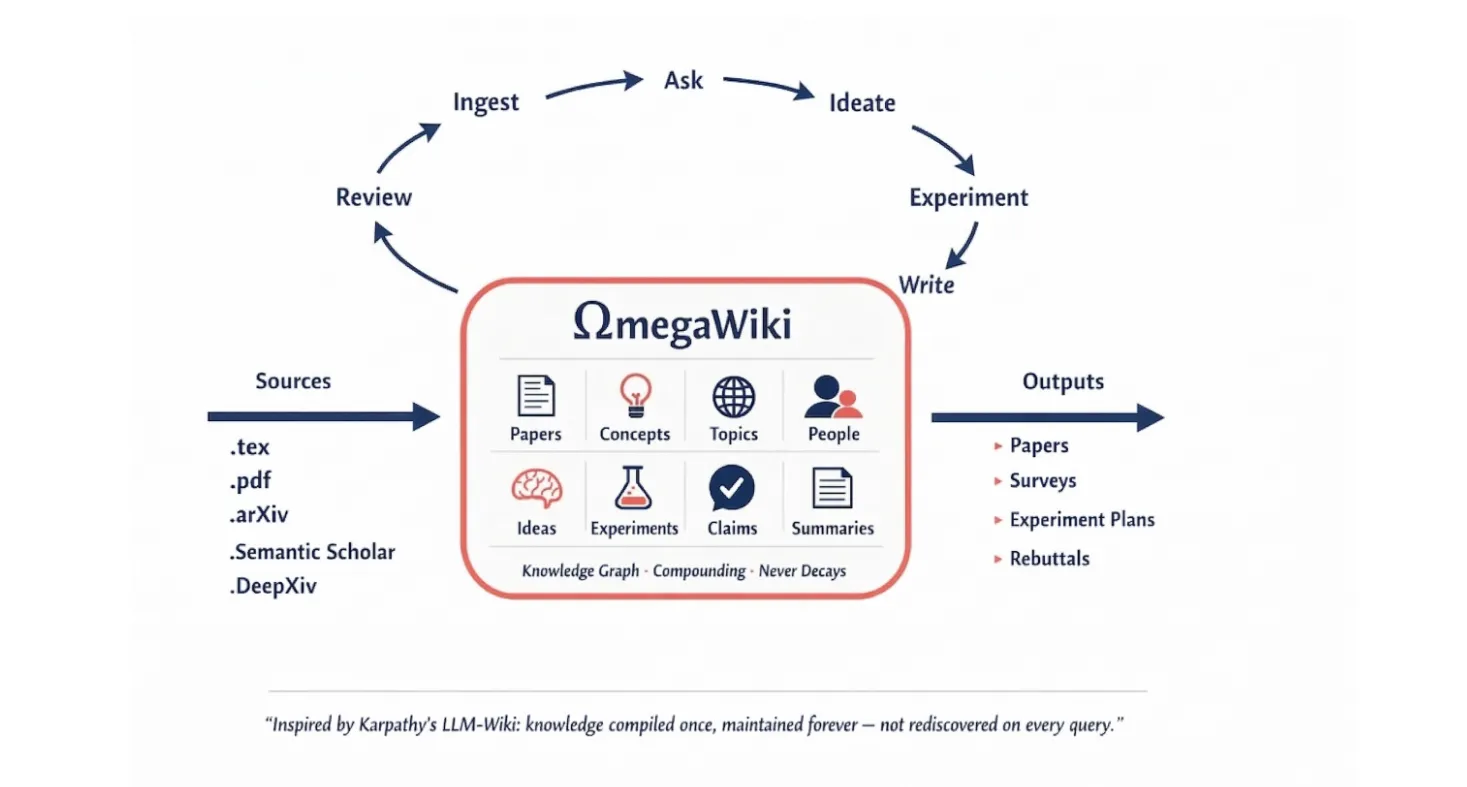
The architecture in the gist has three layers, and each one is deliberately boring. The first layer is your raw sources — PDFs, articles, meeting notes, bookmarks. These stay untouched; you just drop things in, and nothing you ingest gets rewritten or destroyed. The second layer is the wiki itself: a folder of markdown files that the LLM writes and maintains, holding summaries, concept pages, entity pages, and cross-references. The model creates links between pages, flags contradictions when new information arrives, and updates earlier entries when you add something new — the corpus edits itself as it grows.
The third layer is the schema — a configuration file (e.g. a CLAUDE.md for Claude Code or an AGENTS.md for Codex, to use the gist's own examples) that tells the AI how to organize the wiki, how to ingest new sources, and how to format answers. This is the operating manual that keeps the whole system coherent across hundreds of ingests. The human's job is to decide what goes in and to ask good questions; the LLM does the bookkeeping. That division of labor is the whole idea.
Why It's Different from RAG and Traditional Note-Taking
RAG retrieves. The LLM wiki accumulates. That's the real distinction, and it's worth dwelling on because everything else follows from it.
Traditional note-taking apps like Notion or Obsidian give you the container but leave all the maintenance to you. You have to tag things, link things, and update things — and most people's Notion databases are full of pages nobody has touched since month two. The LLM wiki solves the maintenance problem by delegating it: the LLM handles cross-references, flags stale info, and updates connections automatically. As Analytics Vidhya's breakdown of Karpathy's approach explains, the wiki becomes more valuable with each new source you add, because each ingest integrates rather than merely appends.
2. What Made Karpathy's Approach Go Viral
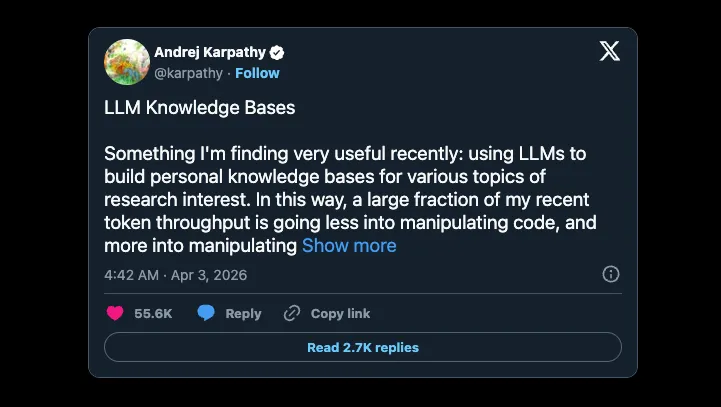
The tweet has drawn roughly 21 million views as of mid-2026, and the follow-up gist passed 5,000 stars within days. That's not normal behavior for an architecture doc.
I think it went viral for two reasons. One: it named a frustration people already had but couldn't articulate. The "rediscovering from scratch" problem is real and annoying, and nobody had given it a clean framing before. Two: it wasn't code. It was an "idea file" — a conceptual pattern you paste into your own LLM agent and let it build out for you. That made it feel immediately usable rather than aspirational.
The Core Insight: Knowledge That Compounds Instead of Resets
This is the sentence that stopped me. From Karpathy's gist: "The tedious part of maintaining a knowledge base is not the reading or the thinking — it's the bookkeeping. Humans abandon wikis because the maintenance burden grows faster than the value. … LLMs don't get bored."
That's it. That's the whole insight. The reason every personal knowledge system eventually collapses isn't that people stop reading — it's that nobody wants to spend Saturday afternoon updating cross-references in Notion. The LLM wiki doesn't ask you to; the LLM does that part, indefinitely, at near-zero marginal cost. That shift — from you maintaining the system to the LLM maintaining it — is a more significant reframe than it first appears.
Farzapedia — What Happens When You Do This With Personal Context
The most interesting real-world example from the viral moment wasn't Karpathy's research setup. It was Farzapedia.
Developer Farza fed 2,500 entries — diary notes, Apple Notes, iMessage conversations — into an LLM and had it compile a personal Wikipedia. The result was 400 interconnected articles covering his friends, companies, projects, and interests, with backlinks and cross-references throughout. Karpathy quote-tweeted it and described the resulting artifact as "explicit and navigable." The point wasn't that the wiki knew more than the original notes; it's that it could be walked. You could actually navigate it, find things, and follow connections. The raw notes were a pile; the wiki was a map.
That example matters because it shows the pattern works well beyond academic research. It works for any domain where you're accumulating knowledge over time — which is most knowledge work.
3. Who It Was Actually Designed For
Here's where I want to be direct, because most of the articles I've seen skip this part.
Karpathy's implementation is for developers. Full stop. His setup requires Claude Code (a terminal-based coding agent), Obsidian, comfort with shell commands, GitHub gist familiarity, and the willingness to debug when things break. Antigravity's deep dive into the LLM Wiki idea file does a good job walking through each tool — and the list is formidable if you're not technical.
This isn't a criticism of the pattern; it's just accurate. Karpathy is a researcher and engineer building a system for how he works. His corpus is academic papers, code, and research documents, and his workflow is a shell with an LLM in it.
Researchers, Developers — vs. Solo Business Operators
The gap between "who this was built for" and "who is excited about it" is pretty wide. Solo founders, content creators, consultants, and operations people read the tweets, got excited about the core insight, then opened the GitHub gist and saw terminal commands. That's where most of them stopped.
The insight is genuinely valuable for anyone who works with large volumes of information over time. The implementation, though, assumes a technical comfort level that most non-developers don't have and don't want to acquire just to manage their notes. For a consultant, that compounding corpus is also the substance clients are actually paying for — which is why where you set your price from day one deserves as much deliberate thought as how you store it.
I'm somewhere in the middle. I can follow the architecture, but I don't want to be debugging a Python script on a Tuesday afternoon when I should be writing.
4. What Solo Operators Can Learn — Without Building Anything
The part of Karpathy's pattern that applies to everyone isn't the tooling. It's the underlying principle.
The Underlying Problem It Solves: Context Loss, Reset Cost
Every time you open a new AI session and have to re-explain your project, your context, your preferences, and your standards — that's a reset cost. It's small per session, and it compounds across hundreds of sessions.
The LLM wiki solves this by making knowledge persistent and explicit: the AI navigates the wiki instead of starting from scratch, and the human curates rather than re-explains. For solo operators who aren't going to build a markdown directory and a schema file, the same principle applies at a simpler level — what's the cheapest version of "compile once, use many times"? That might be a well-structured system prompt you maintain and update, a reference document you paste in at the start of key workflows, or a template that encodes how you work so you don't re-explain it each session. The mechanism is simpler; the compounding is real.
What a Workspace-First Approach Covers Instead
There's also an emerging product category trying to solve this more directly for non-developers — tools built around the workspace model rather than the assistant model, the shift we mapped in our guide to AI workspace agents.
The idea: instead of you bringing context to the AI each session, the AI lives inside an environment where your work already is. Files, browsing, decisions, iterative edits — the context accumulates without you managing it. Tools like Floatboat AI are building in this direction: an AI workspace that learns your working patterns over time rather than starting fresh each session. I haven't run it through enough real workflows to give you a definitive verdict, but the framing matches the problem the LLM wiki is pointing at — compounding context, not resetting it.
5. Should You Build Your Own LLM Wiki?
Let me give you an actual answer.
When Yes Makes Sense
Build one if you're a developer or comfortable with a terminal, you work with a defined corpus of material that grows over time (research, documentation, client files, a beat you cover), and you're going to ingest new sources regularly enough that the maintenance overhead pays off.
The pattern shines for researchers, technical writers, domain-specific analysts, and anyone whose work involves progressively understanding a complex topic. If you have 50+ sources and they keep arriving, a compiled wiki will save you more and more time as it grows.
When the Overhead Isn't Worth It
If you're not technical, the setup cost is real. You need Claude Code or a similar agent, comfort with markdown and shell commands, and a willingness to debug. The gist is brilliant; it is also not beginner-friendly.
If your knowledge base is shallow (under 30–40 sources), or if you're doing varied ad-hoc work rather than deep domain accumulation, the investment probably doesn't return enough to justify it. A well-maintained system prompt and a few reference documents will cover most of the same ground with zero infrastructure.
Lighter Alternatives for Solo Operators
For non-technical users, there's a spectrum of realistic options, and the cheapest end takes about ten minutes to set up. Maintain a living "context document" — 500–800 words describing your current projects, working preferences, and standards — and paste it at the start of important AI sessions, updating it monthly. It isn't as powerful as a compiled wiki, but it addresses the same reset problem and requires no infrastructure at all. The middle ground is tools like Notion AI or ChatGPT's memory feature, which provide partial versions of persistent context: they remember things across sessions to varying degrees, less structured than a wiki but with much lower friction.
At the emerging end, workspace tools like Floatboat — plus the no-code wiki apps that started appearing after April 2026 — are attempting to make the compounding-context pattern accessible without any setup. If you want the full decision framework, I worked through the build-it, buy-a-workspace, or skip-it question in our LLM knowledge base guide for solo operators; the short version is that the right tier depends on how much your work actually accumulates.
6. What the Karpathy Pattern Points to as a Product Category
The gist itself points in this direction. Karpathy notes that as the pattern matures, there's room for a product that makes the ingest, query, lint, and visualization workflow coherent rather than a pile of scripts — the gist lays out that loop explicitly, and it's the loop every hand-rolled implementation ends up rebuilding.
Right now, the community is already iterating fast — adding confidence scoring to wiki pages, supersession logic when new sources contradict old ones, and lifecycle management so knowledge doesn't rot. These are problems that emerge at scale, and they're being solved openly.
What the developer community was building by hand in spring 2026 has already started arriving as products, faster than almost anyone expected. As of September 2026: Readwise shipped a free, open-source app based on the pattern in April 2026, aimed squarely at people who don't run shells; Curated Thoughts is an MIT-licensed desktop app that keeps a Karpathy-style wiki over a plain markdown vault; and MindStudio has published a five-minute, no-code setup. None of these require a terminal. The question this article keeps circling — what about the other 95% of users? — is being answered from both ends: dedicated wiki apps on one side, and AI workspaces on the other, where context accumulates inside the environment you already work in.
That's the product category the LLM wiki points toward. Not a better RAG. A workspace that knows how you work.
7. Conclusion
That's where I am with this. The pattern is genuinely interesting — not because it's revolutionary, but because it finally names the problem clearly and gives it a concrete architecture. Whether you build one yourself depends almost entirely on two things: whether you're comfortable running shell commands (or using one of the no-code apps that now exist), and whether your work actually involves deep domain accumulation over time.
If the answer to the first is yes — or you're happy to let a packaged app do the shell part for you — Karpathy's gist is right there, and the community implementations are already good. If the answer is no, the principle still matters. Figure out your simplest version of "compile once, use many times." That's the part worth keeping.
https://floatboat.ai/blog/what-is-llm-wiki