Best AI Agent Builder in 2026
Best ai agent builder options in 2026 should be compared by setup effort, workflow fit, limits, and maintenance burden.
The best AI agent builder is not the one with the longest integration list or the cleanest demo. It is the one that completes your specific job reliably, exposes enough control for the risk involved, and remains affordable when failures and human review are counted.
That makes a universal ranking misleading. A visual automation builder can be the right choice for routing low-risk requests and the wrong choice for a customer-facing process that needs versioned evaluations. A code framework can provide excellent control and still be wasteful for a three-step internal workflow.
This guide replaces the usual winner list with a reproducible evaluation. You can use the same scorecard for no-code builders, low-code platforms, developer frameworks, and ecosystem-native products without pretending they solve the same problem.
What counts as an AI agent builder?
An automation follows a path you define: when an event occurs, run these steps. An agent has bounded discretion inside that path: it can interpret an input, choose among approved tools, decide whether it has enough information, and stop or request help.
The distinction matters because discretion creates new failure modes. A model call inside a fixed workflow does not automatically make that workflow an agent. Conversely, an agent does not need unrestricted autonomy. In production, the useful pattern is usually a constrained agent surrounded by deterministic validation, permissions, budgets, and approval gates.
Before shopping, write one sentence:
When this trigger occurs, the system may use these data and tools to produce this output, but must ask a person before these consequential actions.
If every step can be known in advance, compare automation tools instead. If the route changes with ambiguous inputs, an agent builder may be justified.
The four builder families
Product labels overlap, so start with the operating model rather than a vendor category.
| Builder family | Best fit | Main trade-off | Examples to investigate |
|---|---|---|---|
| Automation platform with agent features | App-to-app work, event triggers, business users | Fast setup, but complex state and testing may become awkward | Zapier, Make, n8n |
| Visual agent application platform | Knowledge workflows, RAG, internal assistants | More AI-native controls, but deployment and portability vary | Dify, Flowise |
| Developer framework | Stateful or customer-facing systems with custom logic | Maximum control, highest engineering ownership | LangGraph and related SDKs |
| Ecosystem-native builder | Organizations already governed inside one cloud or workplace suite | Strong identity and policy fit, deeper ecosystem dependence | Microsoft Copilot Studio, Google Vertex AI Agent Builder |
These are examples, not a ranking. Product capabilities and commercial terms change. Verify the exact edition, region, connector, deployment option, and usage unit before treating a row as a shortlist.
A seven-part scorecard you can reproduce
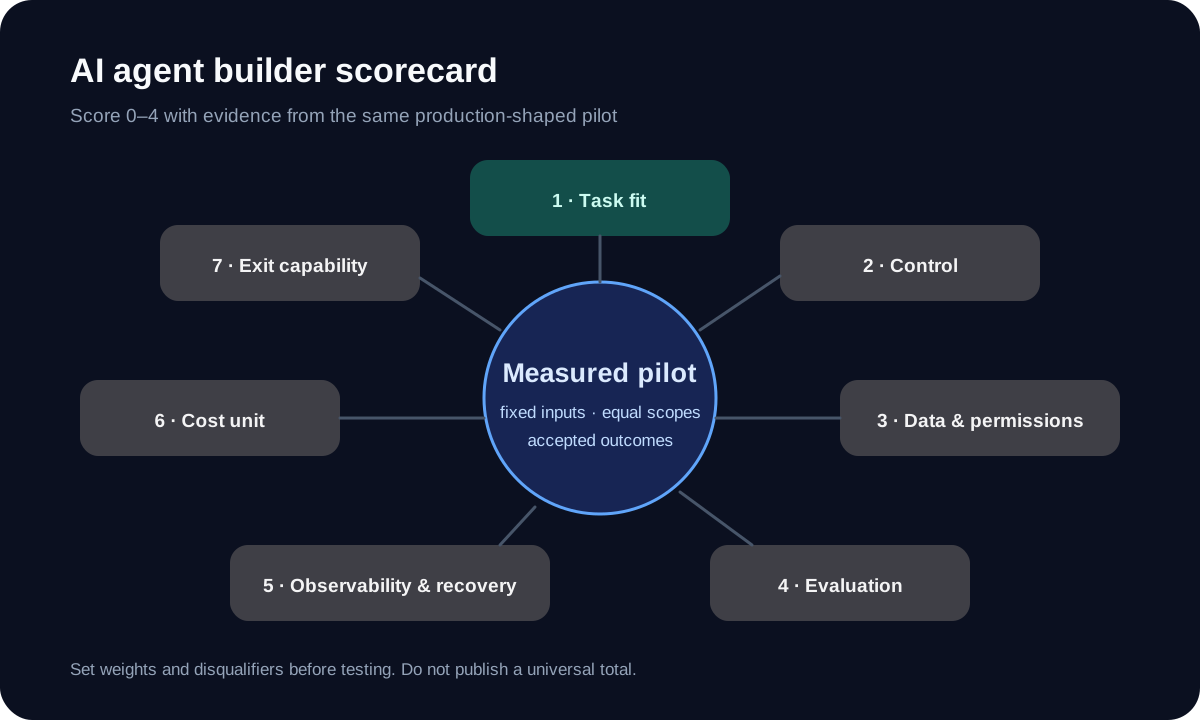
Score each dimension from 0 to 4 using evidence from your own pilot:
- 0 — absent: the requirement cannot be met.
- 1 — manual: possible only through fragile workarounds or recurring manual intervention.
- 2 — workable: meets the normal case, with gaps in control or operations.
- 3 — strong: meets normal and failure cases with documented controls.
- 4 — evidenced: meets the requirement and can prove it through tests, logs, export, or policy enforcement.
Do not add the numbers until you assign weights. A marketing-content assistant and a system that changes customer records should not value permissions equally.
1. Task fit
Build the actual workflow, not a vendor tutorial. Test whether the builder can represent required triggers, state, tool selection, structured outputs, retries, and human handoffs without hiding critical logic in one enormous prompt.
Score the acceptance rate on a fixed dataset. “It produced an answer” is not success; define what a correct outcome contains and what must never happen.
2. Control
Check whether you can restrict tools, input fields, domains, actions, run length, and spend. A useful approval gate shows the proposed action and relevant context, then resumes from stored state after a decision. A chat message asking “Are you sure?” is not enough if the underlying tool can still execute without authorization.
LangGraph's official documentation, for example, describes checkpoints, interrupts, retries, and resumption as explicit graph behavior. That is evidence about a design capability—not proof that an application built with it is safe by default.
3. Data and permissions
Map every hop: trigger, builder, model provider, knowledge store, observability service, connected app, and export destination. For each hop, record authentication method, scopes, retention, region, training policy, encryption options, and deletion path.
Also test authorization at run time. Microsoft documents tenant- and environment-level data policies for Copilot Studio, including connector grouping and blocked endpoints. That can be valuable for a Microsoft-governed organization, but you still need to configure and test those policies for your agent.
4. Evaluation
A prompt preview is not an evaluation system. Look for versioned datasets, repeatable runs, pass/fail criteria, comparison between revisions, and a path for production failures to become regression cases.
LangSmith's official evaluation documentation separates offline tests—such as regression testing and backtesting—from online monitoring. Whatever platform you choose, insist on both: pre-release evidence and post-release detection.
5. Observability and recovery
For a failed run, can an operator answer these questions without guessing?
- Which version ran?
- What input and retrieved context influenced it?
- Which tools were attempted, with what arguments and responses?
- Where did it stop, retry, or branch?
- Can the run be safely resumed or replayed without duplicating side effects?
Status dashboards alone are insufficient. You need usable traces, redaction controls, alerts, and an incident path. Also ask how long traces are retained and whether exporting them changes the data boundary.
6. Cost unit
Never compare only subscription prices. Builders meter different things: activities, workflow executions, operations, messages, tokens, seats, or combinations of them. Zapier's official help center, for example, defines an Agent activity as a billable action and notes that triggers, knowledge lookups, actions, browsing, and searches can each consume activities. That is a different cost shape from a product that meters an entire workflow execution.
Calculate cost per accepted outcome:
(platform + model + connected tools + infrastructure
 + human review + retries + incident handling)
÷ accepted outcomes
Run the calculation at current volume, expected volume, and a burst scenario. Include failed and duplicate runs. A cheap successful run can still be an expensive business outcome if it often needs repair.
7. Exit capability
Export one working agent during the trial. Check separately whether you can retrieve prompts, workflow logic, tool schemas, test datasets, run history, knowledge sources, secrets references, and state.
An export file is not portability if only the original service can interpret it. For visual builders, inspect whether the format is documented and suitable for version control. For code frameworks, confirm that deployment, checkpoints, traces, and evaluation data are not separately locked to a hosted service.
Run the same pilot on every candidate
Choose one bounded workflow with a measurable outcome. A useful test might classify an inbound request, retrieve an approved policy, draft a structured response, and route it for approval. Do not let the agent send the response during the first pilot.
Create a test pack of at least these input classes:
- normal, complete requests;
- missing required information;
- conflicting instructions;
- duplicate events;
- unavailable or rate-limited tools;
- stale knowledge;
- malicious text that attempts to override instructions;
- cases that must be escalated.
Give every candidate the same tool scopes and source material. Freeze model versions where possible. Record configuration time, accepted outcomes, unsafe actions, unnecessary escalations, median and tail latency, cost-unit consumption, review time, and repair time.
Do not declare a winner from one pass. Change a prompt, model, connector, or workflow step, then rerun the pack. The ease of detecting a regression is part of the product evaluation.
How to weight the scorecard by use case
The weights—not a generic league table—produce the decision.
| Use case | Give extra weight to | Usually tolerate less of |
|---|---|---|
| Internal drafting | Task fit, cost, setup speed | Elaborate deployment controls |
| Cross-app operations | Recovery, idempotency, connector reliability | Opaque execution units |
| Customer-facing assistant | Evaluation, observability, data controls | Unversioned prompt changes |
| Regulated workflow | Permissions, auditability, approval, retention | Broad default scopes |
| Custom product feature | Control, testability, portability | Proprietary logic with weak export |
For a high-impact workflow, make any zero in permissions, evaluation, or recovery a disqualifier instead of averaging it away.
Questions to ask vendors and open-source maintainers
Ask for a demonstration using your failure cases, not a prepared happy path:
- Can a tool be granted read access without write access?
- Can approvals be required by action type, data class, or spend threshold?
- What exactly is recorded in a trace, and who can view it?
- How are secrets separated across development and production?
- Can a released version be rolled back with its prompts and tool schemas?
- What happens when a run times out after an external side effect?
- Which usage events are billable, including tests and retries?
- Can we export logic, state, evaluation sets, and logs in usable formats?
- Which controls require a higher plan or a particular deployment model?
A vague answer is itself evidence for the scorecard.
Common selection mistakes
Counting integrations instead of testing two critical ones. A connector logo does not prove support for the exact trigger, object, field, authentication scheme, or rate limit you need.
Treating self-hosted as automatically private. Self-hosting one layer does not keep data local if the workflow sends prompts, traces, embeddings, or documents to other services. Follow the complete data path.
Testing only clean inputs. Agents fail at ambiguity, duplication, stale context, and conflicting instructions—not only when an API is down.
Scoring build speed but not change safety. The second version matters more than the demo. Evaluate regression tests, version history, rollback, and recovery.
Using autonomy as the goal. The desired outcome is reliable work at an acceptable risk and cost, not the largest number of decisions delegated to a model.
A practical selection process
- Define one workflow, accepted outcome, prohibited actions, and escalation owner.
- Choose one candidate from each relevant builder family; exclude categories that do not fit your operating model.
- Set weights and disqualifiers before testing.
- Run the fixed adversarial test pack with identical permissions.
- Calculate cost per accepted outcome, including review and repair.
- Perform the exit test and one rollback or recovery exercise.
- Select the builder only for that workflow, then repeat before expanding scope.
If your task is primarily deterministic, read our guide to choosing a no-code AI agent builder with the automation-versus-agent boundary in mind. If you are comparing the wider operating layer rather than authoring tools alone, the AI agent platform guide covers deployment and governance questions.
Bottom line
There is no defensible “best AI agent builder in 2026” without a workflow, risk level, and operating model. The best builder for you is the candidate that clears your disqualifiers, performs best on a fixed test pack, makes failures diagnosable, and lets you understand both the cost of running it and the cost of leaving it.
That answer may be a no-code platform, a visual AI environment, a developer framework, or no agent at all. A reproducible selection is more useful than a universal ranking—and much easier to defend after the demo.
Official references used for the framework
- Zapier: how Agents usage is measured
- LangGraph: state, retries, durable execution, and human input
- LangSmith: offline and online evaluation types
- Microsoft: configure data policies for Copilot Studio agents
Product documentation confirms capabilities, not fitness for your environment. Recheck the current documentation, plan entitlements, and contractual terms during procurement.
https://floatboat.ai/blog/best-ai-agent-builder-2026