What Is MiniMax H3 — The Open Omni-Modal Video Model
MiniMax H3 is an open-weight omni-modal video model that turns text, images, clips, and audio into 2K video with native stereo sound. Capabilities and limits.
Information checked October 13, 2026. Specifications, hosted prices, model files, and license terms are time-sensitive; verify the linked MiniMax sources before deployment.
TL;DR
-
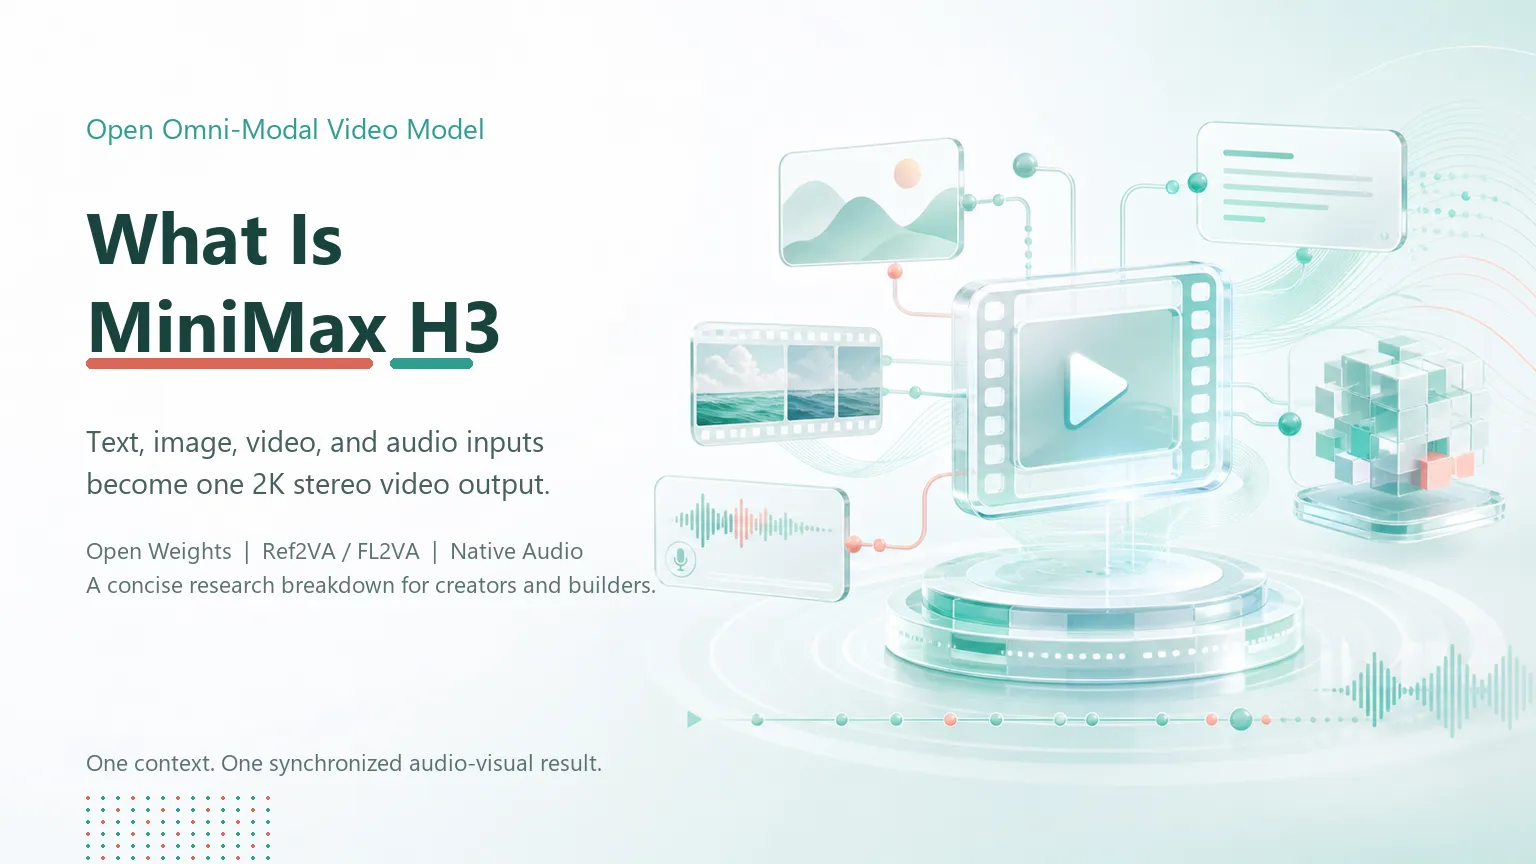
MiniMax H3 is an omni-modal video generation model — a single open-weight system that reads text, images, video, and audio as one context and returns a finished clip with synchronized stereo audio in a single pass, as released on Hugging Face.
-
It generates video up to 2K resolution and 15 seconds at 24 FPS, with 32 kHz stereo audio produced by the same diffusion transformer rather than dubbed in post.
-
Two checkpoints are released: FL2VA (text / first-frame / last-frame to video) and Ref2VA (reference-to-video with up to 9 images, 3 clips, and 3 audio files in one request).
-
Pricing starts at $0.13 per second at 2K and $0.08 per second at 768p , per the official MiniMax pricing page.
-
Open weights cover H3-Base only: the H3-Context-IR preprocessing module and the 2K regeneration module remain API-only for now.
1. Why a General-Purpose Video Model Changes the Game
Video generation has spent two years fragmenting into specialist tools. You use one model for text-to-video, another for image-to-video, a third for editing an existing clip, a fourth for motion transfer, and a separate pipeline for voice, sound effects, and music that gets composited in post. Each of those tools understands a narrow slice of your intent, so real production work means stitching five services together and hoping the pieces agree on what the subject looks like, how the camera moves, and what the scene is supposed to feel like.
MiniMax H3 combines text, reference images, reference clips, and audio in one documented input system and generates an audio-visual result. That is the defining capability to test. It does not establish superiority over specialist tools; use the same assets and acceptance rubric when comparing workflows. TypeSafe's Jev illustrates the opposite design choice—a narrowly scoped model—without implying that either architecture is universally better.
The pattern is familiar to anyone who watched the LLM category consolidate: frontier labs raced to define the categories first, then open weights arrived and the ecosystem — inference frameworks, hardware vendors, community workflows — caught up within days. Video generation is now at the same inflection, and H3 is the first serious omni-modal model to ship its weights rather than keep them behind an API. We wrote a similar breakdown when Kimi K3 opened its frontier-model weights; H3 is the video-side version of that story.
2. MiniMax H3 Defined
2.1 The Core Definition
MiniMax H3 is a general-purpose, omni-modal generative system. It takes a multimodal context made of text, images, video, and audio, understands the relationships between those inputs, and generates a video with native stereo audio in a single pass. "Omni-modal" here is not a buzzword — it means the same transformer predicts both the visual latents and the audio latents, so the soundtrack is generated jointly with the picture instead of being added afterwards.
2.2 Output Specifications
Specification | Value |
Output duration | 4–15 seconds |
Output resolution | Short side 768p by default; 2K via the regeneration module |
Frame rate | 24 FPS |
Audio | 32 kHz stereo, generated with the video |
Aspect ratios | 21:9, 16:9, 4:3, 1:1, 3:4, 9:16 and more |
Supported languages | 11 stable: Arabic, Chinese, English, French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish |
2.3 What H3 Is Not
The model card documents output up to 2K through the regeneration path; it does not document a 4K path. Ref2VA accepts up to twelve mixed reference assets — images, clips, and audio — and uses them as one generation context. That makes H3 a multimodal generation-and-editing system whose inputs can resemble a production brief rather than a single caption.
3. How MiniMax H3 Works
The full H3 system is three modules. H3-Context-IR is a hosted preprocessing and orchestration layer that interprets a free-form multimodal brief and serializes it into a structured intermediate representation. H3-Base is the open-weight generator that takes that representation and produces a 768p audio-visual result. H3-Regenerate-2K feeds the 768p output and original context back through the generation system to produce the documented 2K result. The published materials describe the pipeline, but they do not remove the need to test fine detail, text, motion, and audio synchronization on your own assets.
Under the hood, H3-Base is a 33-billion-parameter dense, single-stream transformer, roughly 13B of those parameters living in adaptive layer-norm (AdaLN) branches that can be precomputed and cached at inference time, as documented in the Hugging Face model card. Text is encoded by an H3-Encoder built on the full pretrained weights of Qwen3-VL-32B; visuals pass through a temporally causal H3-VisualVAE (16× spatial and 4× temporal compression, 24 latent channels); audio goes through an H3-AudioVAE that compresses 32 kHz audio into a 40 Hz token stream with separate encoding and decoding per stereo channel. The transformer uses three-dimensional multimodal rotary position embeddings (MM-RoPE) to represent positions across time, height, and width, and natively supports sparse attention for long sequences — though the open release runs full attention, with the sparse-attention implementation promised in a future update. The instinct behind that caching — pay full compute only for what actually varies — is the same one behind effort control for AI work: match the compute budget to the step instead of paying peak price for every token.
The design choice worth noting is that attention and feedforward layers contain no modality-specific structure. All modality specialization lives in the input/output layers and the AdaLN branches. That is why a single model can switch between text-to-video, first-and-last-frame generation, and twelve-asset reference generation without architectural surgery — and why MiniMax could distill the whole thing down to task-specific checkpoints that each ship with their own processor, tokenizer, text encoder, visual VAE, and audio VAE.
4. How to Compare H3 With Other Video Models
Do not turn vendor specifications and third-party impressions into a universal ranking. Compare H3 with the alternatives available to your account using the same prompts, reference assets, duration, resolution, and acceptance rubric. Score subject continuity, instruction adherence, motion, audio synchronization, artifact rate, regeneration rate, latency, and total cost per accepted clip.
MiniMax’s current official pricing page lists H3 at $0.08 per output second for 768p and $0.13 for 2K. It also lists charges for additional images, input video, 2K regeneration, and Context-IR. Those fees belong in the comparison; multiplying the headline output rate by duration alone can understate a reference-heavy workflow.
The official model card supports a defensible H3 feature summary. Competing products should be checked against their own current documentation rather than an unsourced cross-vendor table. If the broader decision is whether a frontier capability should remain vendor-hosted, GPT-6 Astra’s deployment boundaries offer a useful contrast, but not a video-quality benchmark.
5. What "Open Weights" Actually Includes
Open weight releases in video generation have a credibility problem, because past promises often turned out to mean "a blog post and a waitlist." H3's release is real but partial, and the distinction matters if you are planning a local deployment. What is downloadable from the MiniMaxAI/MiniMax-H3 repository is the H3-Base module, distributed as two task-specific checkpoints (FL2VA and Ref2VA), each self-contained with its processor, tokenizer, text encoder, visual VAE, and audio VAE. The model is served through SGLang, vLLM, diffusers, and ComfyUI, with a recommended four-GPU setup, and hardware compatibility was a stated design priority from the start, with working adaptations across major chip vendors — including Huawei Ascend, AMD, and Intel — and inference platforms such as Hugging Face, ModelScope, and ComfyUI arriving on launch day, as shown in the vLLM recipes entry for H3.
What is not open is the rest of the system. H3-Context-IR is a hosted, multi-stage workflow that depends on multiple MiniMax services, so it stays behind an API; H3-Regenerate-2K is likewise not yet released, with an API provided to validate official 2K results. The released checkpoints run full attention; the sparse-attention implementation that makes long-context inference cheap is scheduled for a future update. Practically, this means a developer can deploy H3-Base locally and reproduce 768p results, and can combine local generation with the Context-IR API to approximate the full 2K workflow — but the complete end-to-end experience is still partly hostage to MiniMax's servers.
Licensing is the other half of "open." H3 is released under the MiniMax H3 Community License, which permits free non-commercial use and commercial use for organizations under $20 million in annual revenue with attribution requirements, as detailed in the official MiniMax H3 license text. That threshold covers most indie studios and freelancers but is a real constraint for funded teams, so read the license text before building a product on top of it. As with any open-weights model, "downloadable" and "commercially unrestricted" are different questions.
6. What H3 Gets Wrong
The documented limits are clearer than informal quality rankings: output lasts 4–15 seconds, the hosted full workflow reaches 2K through regeneration, and the downloadable H3-Base path is not the whole hosted system. Visual fidelity, text rendering, motion, and audio synchronization should be tested with fixed prompts and reference assets; every generated clip still needs QA.
Local deployment of H3-Base does not reproduce every module in the hosted workflow. Teams should test the downloadable path and hosted Context-IR/regeneration path separately rather than assuming equivalent output.
7. Who Should Use MiniMax H3
Whether H3 fits advertising, e-commerce, interface demos, or character-reference work cannot be established from the model card alone. Build a fixed asset set for each job, then score readability, subject continuity, audio-video synchronization, regeneration count, and human correction time. Compare the hosted Context-IR and regeneration path separately from the downloadable H3-Base path because they are not the same system boundary.
Solo operators and studios should calculate cost per accepted clip from output duration, reference-material charges, regeneration, compute, and review time. The related MiniMax H3 Max live-streaming page covers a different workload and should not be used as evidence for H3 clip quality.
8. Conclusion
MiniMax H3 is a distinct tool shape: one system accepts several media types and generates video with native audio. Its value should be decided by a controlled asset test, full workflow cost, deployment requirements, and license terms—not by a claim that it wins a resolution or price race.
For a small team, the practical takeaway is to run a single five-second test clip before committing to an API or a self-host setup: check subject consistency, camera motion, and audio in that order, then add references. And if you are curious about the broader pattern — open frontier weights landing in mainstream creative workflows — our breakdown of the Kimi K3 open frontier model and the vibe-coding, one-prompt game post cover the other two ends of that arc. On the agent side, the same "one system, unified context" philosophy is what drives an agentic calendar — the idea that your context is the runtime, whether the output is a video or a work week.
Related posts
GPT-6.1 Sol: Pricing, Benchmarks, Availability, and How It Compares
GPT-6.1 Sol brings near-Astra coding, computer use, and professional-work performance at one-fifth of Astra's token prices. Here is what…
What Is Jev? The AI Model That Never Writes Text
Jev is TypeSafe AI's System One model: typed probabilistic decisions instead of generated text, claimed 193.6x faster and 444.6x cheaper.…
DeepSeek V4.1 Flash: Release Status, Specs, Pricing, and Migration
DeepSeek V4.1 Flash is now the production Flash model. Verify its model ID, 1M context, vision support, peak pricing, retired aliases, and…
https://floatboat.ai/blog/what-is-minimax-h3